
"Memory Demand Could Increase 10,000 Times"... Exynos CEO Kim Jin-young Diagnoses Memory Bottlenecks in the AI Era
Kim Jin-young, CEO of semiconductor startup Exynos, explains how the surge in AI model size, user numbers…
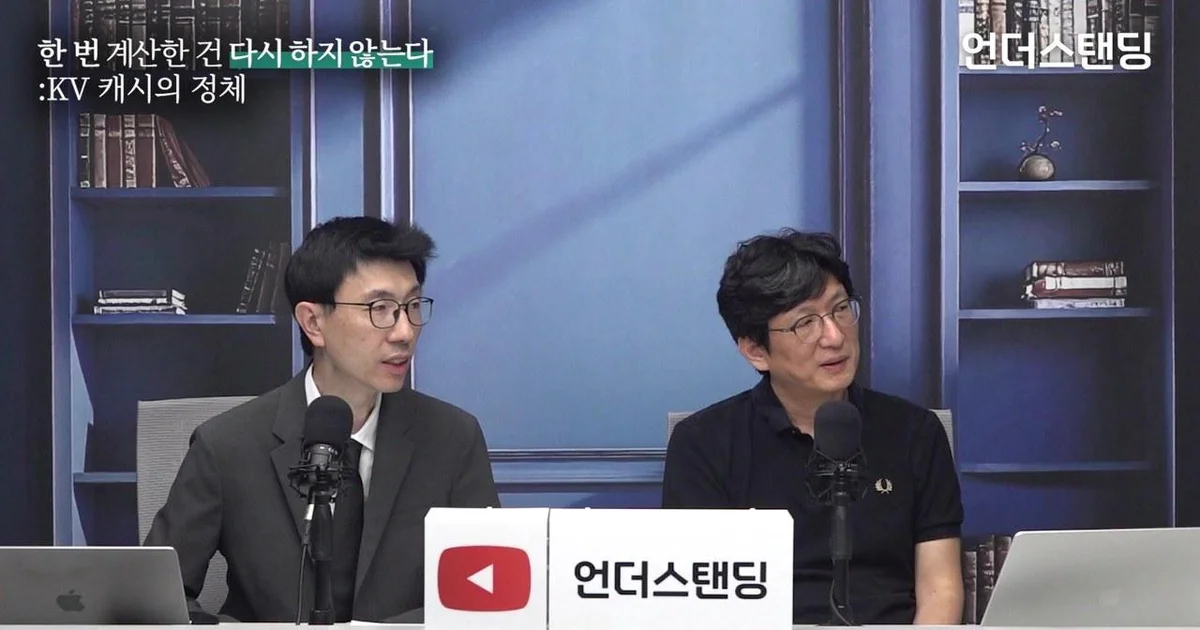
As the era of Artificial Intelligence (AI) enters full swing, memory demand is exploding as data throughput and model sizes grow exponentially. In particular, as the amount of data generated by AI increases and the memory required to maintain conversational context grows, warnings are emerging that it will be difficult to resolve memory bottlenecks using existing methods.
According to a video released on the YouTube channel 'Understanding: All the Knowledge in the World', Kim Jin-young, CEO of the semiconductor startup Exynos, diagnosed that memory lies at the center of AI infrastructure. Kim explained, "AI is a tool that finds value in the data accumulated by humanity," adding, "Because money is made by accumulating and computing more data, massive infrastructure investment is required to support this, and the core of that is memory."
Surge in Models, Users, and Context... "Memory Demand Could Increase 10,000 Times"
Kim identified four key factors for the explosion of memory demand in the AI era: ▲Expansion of AI model size ▲Increase in the number of users ▲Exponential increase in input data (context) length ▲The arrival of the 'Agentic AI' era where multiple models collaborate. Because these factors do not increase independently but act in a way that they are multiplied by each other, memory requirements increase exponentially rather than arithmetically.
In particular, Kim stated, "AI is designed in a structure where the intermediate results to obtain a single answer must be continuously accumulated in memory," and "In the past, it was enough to remember only what humans input, but now AI must remember everything including its own answers and the context, so much more memory is needed." Citing the views of past experts, he predicted, "There are claims that 1,000 times more memory might be needed, but considering the current pace of development, 1,000 times might even be a conservative figure."
This surge in demand leads to the importance of 'Key-Value Cache' technology. Key-Value Cache is a technology that stores previous computation results in memory to be reused so that the GPU does not have to repeat the same computation every time. Kim explained, "Since GPU computations are very expensive and time-consuming, it is efficient to store what has been calculated once in memory and refer to it," and "As conversations get longer, more Key-Value Cache is required, which directly leads to pressure on memory capacity." In fact, as conversations with users grow longer, the amount of Key-Value Cache references required to remember previous content increases, which becomes a key factor in determining infrastructure efficiency.
Doubling Cloud Efficiency with CXL-based 'Memory Pooling'
HBM (High Bandwidth Memory), a core solution for current AI infrastructure, is a technology that maximizes data transfer speed (bandwidth) by physically placing the GPU and memory close together. However, since HBM must be placed within the same package as the GPU chip, there are limits to increasing capacity indefinitely. A technology gaining attention as an alternative to this is CXL (Compute Express Link).
CXL is a next-generation connection standard that connects various devices such as CPUs and GPUs into one. The technology that Exynos focuses on is 'Memory Pooling' technology, which utilizes CXL to allow multiple servers to share memory as if it were a single common space. According to the video, the memory utilization rate in existing cloud environments remains at an average level of 35%. By applying Exynos's technology, this utilization rate can be increased to nearly double.
Kim explained, "By allowing the necessary server to directly access shared memory without copying and moving data, we can secure the same performance with half the CAPEX." As CPUs and products supporting CXL 3.0 are expected to be released to the market from the end of this year or early next year, the market is expected to enter a full-scale opening stage.
Strategy for 'MX1', an Intelligent Memory Chip that Minimizes Data Movement
Exynos is pursuing a strategy to not only expand memory capacity but also to reduce the amount of data movement itself. The core of this is 'MX1', an intelligent memory chip that filters only the necessary data near the memory and even performs simple computations.
While existing methods required transporting large amounts of data individually to computing units (such as GPUs), using MX1 allows data to be processed at the memory level as a primary step. The plan is to alleviate data bottlenecks in the overall infrastructure and increase efficiency through this. Kim stated that they are focusing on technology that can immediately solve the biggest bottlenecks currently faced by data centers.
0Comments
Comments are currently disabled.